RTX 5090 Benchmark: Flux.2 Dev Performance in FP8 and GGUF
Local AI inference performance is traditionally evaluated through a binary metric: whether a model fits entirely within physical VRAM. In…
Local AI inference performance is traditionally evaluated through a binary metric: whether a model fits entirely within physical VRAM. In…
While our initial LTX-2 technical guide covers the deployment fundamentals, professional exploitation of Lightricks’ model requires a granular understanding of quantization formats….
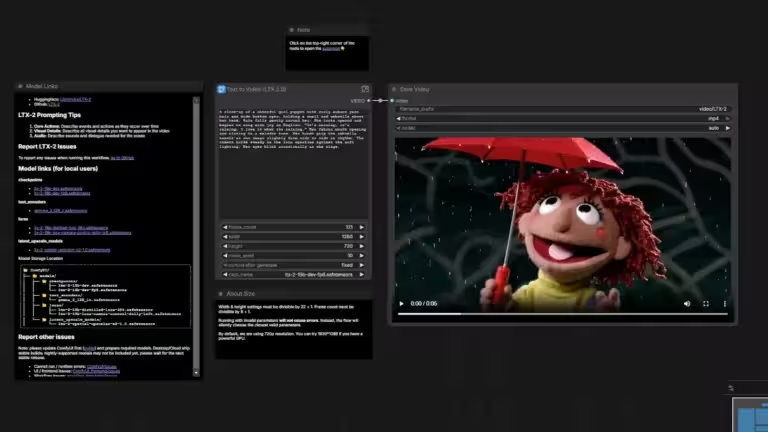
Released in January 2026, the LTX-2 model represents a major leap forward in the local video generation ecosystem. Developed by Lightricks, this…
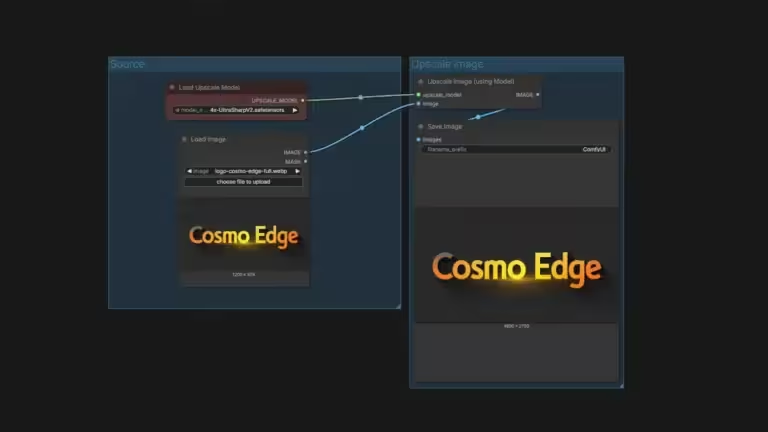
Optimizing images in ComfyUI relies on a precise selection of upscale models, as each architecture, whether ESRGAN-based or more recently…
The year 2026 marks a turning point where the GGUF format is no longer an experimental alternative, but an absolute…
The year 2026 marks a major transformation in how we consume local generative AI, as downloading a model is no…